Max Chagoya
What is NetworkX Graph Visualization
NetworkX graph visualization is the process of displaying graphs created or analyzed with the NetworkX Python package as node-link diagrams. Nodes represent entities, while edges represent the relationships between them. NetworkX layout functions calculate where nodes appear in the drawing, and its Matplotlib-based drawing functions render the graph.
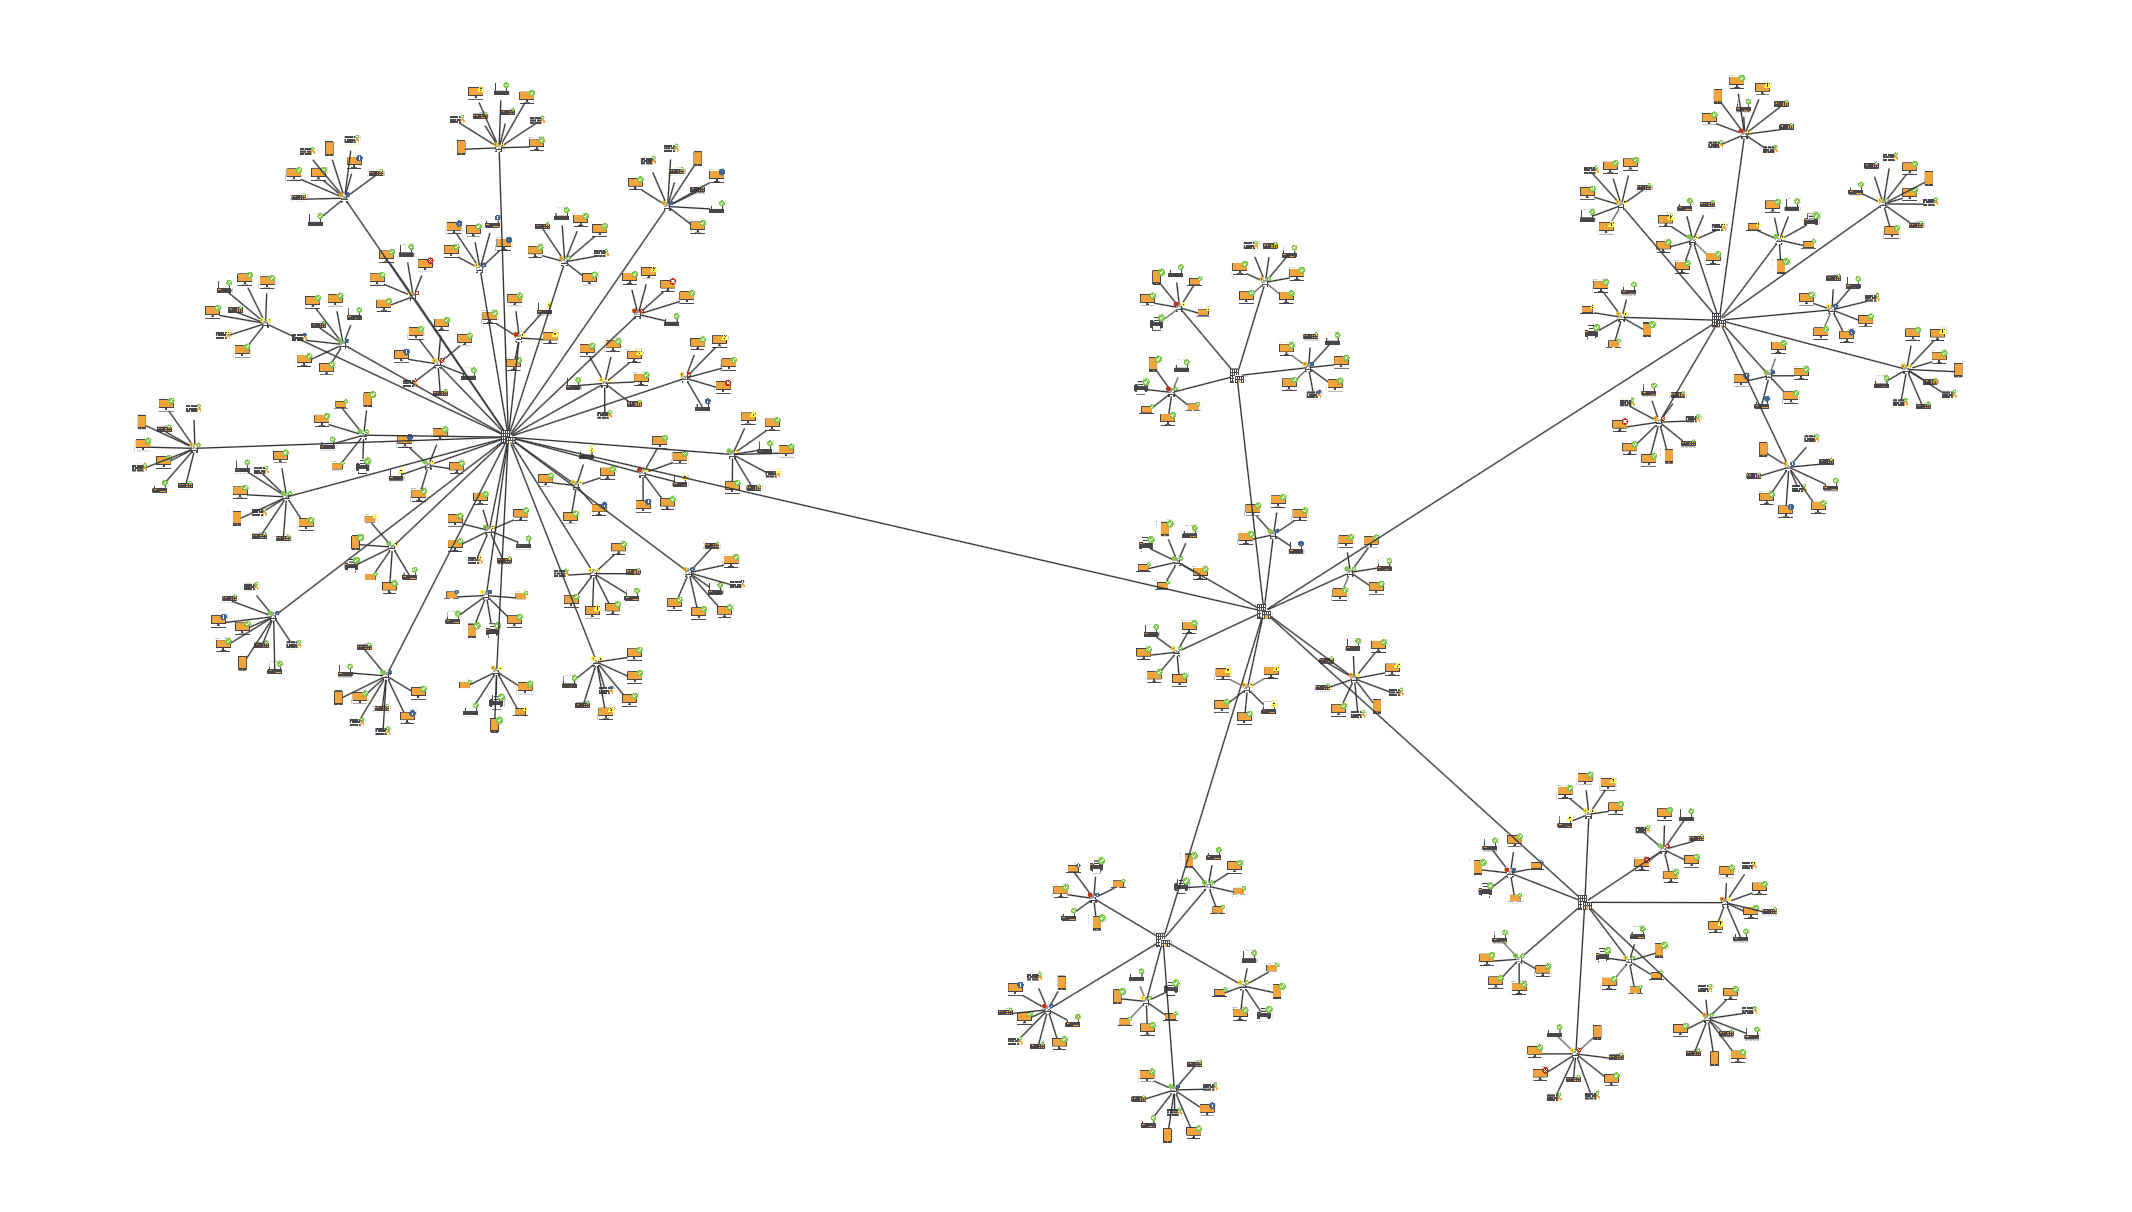
Graph visualization of a retail system, showing patterns.
In social network analysis, a visualization can help an analyst examine how connections are distributed and where groups are linked through a small number of participants. Similar questions arise in biological network analysis, where researchers study interactions between proteins, and in information science, where links connect documents or other information resources. The drawing provides a way to inspect these relationships, while graph algorithms establish properties that cannot reliably be inferred from appearance alone.
Key Features of NetworkX graph visualization
NetworkX can be installed with pip and used directly in a Python script or notebook. A developer can begin with a small graph and inspect it visually as the model takes shape. Because the graph remains available as a Python object, analysis results can be used to change the drawing without reconstructing the underlying network.
NetworkX supports graph models that preserve relationship direction and separate connections between the same entities. Choosing the appropriate model keeps those distinctions available for analysis and visualization, rather than losing them when the source data is converted into a graph.
NetworkX also works with data structures used by other Python data analysis and visualization libraries. A Pandas DataFrame can supply an edge list with relationship attributes, while a NumPy array can represent an adjacency matrix.
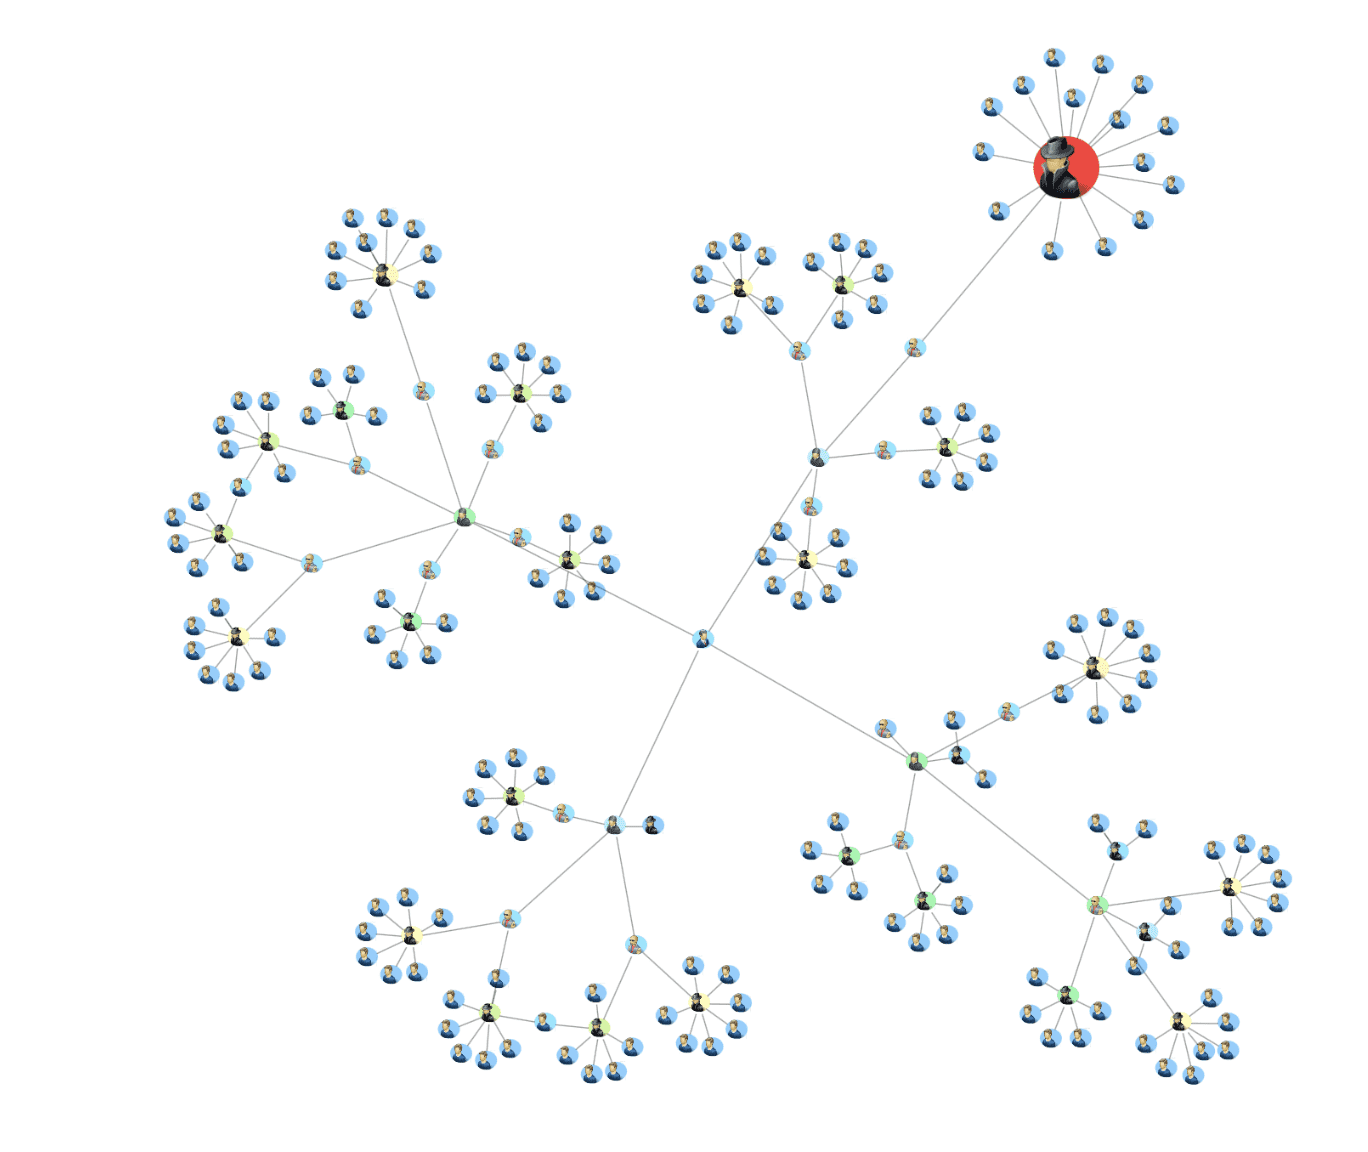
A criminal network graph with page rank applied, showing natural clusters.
Basics of Graph Theory
A NetworkX graph describes entities through nodes and their relationships through edges. In a software dependency graph, each node might represent a package, while an edge records that one package depends on another. Node attributes can identify the installed version, and edge attributes can describe the dependency requirement. These attributes preserve information about the system that its connections alone cannot express.
The relationship determines whether the graph should be directed or undirected. A dependency has a defined direction: package A depending on package B does not imply that B depends on A. An undirected edge instead records a connection without distinguishing a source from a target, as in a mutual friendship. This choice affects how algorithms interpret the graph and which routes can be followed through it.
Degree describes a node’s local connectivity. In an undirected graph, it counts incident edges, with a self-loop counted twice. Directed graphs distinguish incoming connections through in-degree and outgoing connections through out-degree. A high degree indicates many edge connections, but its significance depends on what those edges represent. When edges point from each package to its dependencies, a high in-degree indicates that many packages depend on it, while a high out-degree indicates that it depends on many others.
Paths describe how nodes are connected through successive edges. If package A depends on B and B depends on C, the directed path from A to C shows an indirect dependency. A change to C may therefore affect A through B. A cycle returns to its starting node without repeating intermediate nodes, exposing a circular dependency in this example. Whether a cycle is problematic depends on the system being modeled; in other networks, it may represent an expected feedback mechanism.
Edge weights add numerical meaning to a relationship. A transportation graph might use distance as its weight, allowing a shortest-path calculation to compare total distance rather than the number of connections. Both directed and undirected graphs can be weighted. In an unweighted analysis, connections are treated equally for the calculation, even though the edges may still carry descriptive attributes.
Creating NetworkX Graph Visualization
Creating a NetworkX graph starts with initializing the appropriate graph class, such as nx.DiGraph() for directed relationships. Developers then use add_node() and add_edge() to add entities and relationships from the source data, together with the attributes needed for analysis. In a social network, a node might store a person’s location, while an edge records interaction frequency. These attributes can later determine how elements appear in the drawing.
NetworkX’s standard drawing functions use Matplotlib to render the graph. A layout function such as nx.spring_layout() calculates node positions, which can be passed to nx.draw() through its pos parameter. Changing the layout changes the drawing without changing the underlying relationships.
NetworkX Graph Types
NetworkX provides four primary graph classes. The appropriate class depends on edge direction and support for parallel edges.
|
NetworkX Class |
Direction |
Parallel Edges |
Example |
|
Graph |
Undirected |
No |
Mutual friendships |
|
DiGraph |
Directed |
No |
Package dependencies |
|
MultiGraph |
Undirected |
Yes |
Separate physical links between two sites |
|
MultiDiGraph |
Directed |
Yes |
Individual transactions from one account to another |
Parallel edges preserve distinct relationship records between the same endpoints. A MultiDiGraph can retain several transfers between two accounts, each with its own amount and timestamp. A DiGraph stores one edge per ordered pair of nodes, so repeated transfers would need to be aggregated or represented through another modeling approach.
Weighted and unweighted graphs are not separate NetworkX classes. Any of these classes can store a numerical edge attribute such as distance or interaction frequency. The selected algorithm and its parameters determine how that value is interpreted.
Interactive and 3D NetworkX Graph Visualizations
A graph constructed in NetworkX can also serve as the model behind an interactive graph visualization. Its layout coordinates and analytical results can be passed to a rendering library, where users can inspect individual elements without displaying every detail at once. NetworkX supplies the graph model and calculations, while the visualization library handles the display and user interactions.
NetworkX with Plotly
Plotly can display NetworkX layout coordinates as scatter traces, with markers representing nodes and line segments representing edges. Node attributes can be included in hover text, making details available on demand instead of placing a permanent label beside every node. Users can zoom and pan through the resulting browser-based view while retaining the visual mappings defined for the graph.
A continuously updated view requires an application to connect incoming data to the visualization. When a relationship changes, the application must update the graph and refresh the affected display data. Analytical values or layout positions may also need to be recalculated, depending on the change.
NetworkX with Bokeh
Bokeh provides a from_networkx() helper that creates a graph renderer from a NetworkX graph and a layout function or position dictionary. The renderer can be configured with hover tools and selection behavior. For example, selecting a node can highlight its connected edges, helping users follow relationships through a dense view.
These interactions can be incorporated into web applications and dashboards. Callbacks define how the application responds to a selection or control, such as displaying attributes for the selected entity or updating the visible data. The developer determines how those actions relate to the underlying NetworkX graph.
3D NetworkX Graph Visualization
NetworkX layout functions that support three dimensions can generate coordinates for a 3D renderer. spring_layout() accepts dim=3, allowing its output to be used to position nodes in a Plotly 3D figure.
Positions calculated by a force-directed layout describe an arrangement of the network; they do not establish the physical locations of its entities. Where source data contains meaningful spatial coordinates, those positions may instead provide the basis for the view. Rotation can expose connections hidden from one angle, although occlusion and label placement still affect readability.
Visualizing NetworkX Graph Analysis Results
NetworkX graph analysis produces results that can be examined within a visualization. A calculated node score can determine node size, allowing an analyst to inspect that score alongside the surrounding relationships. The analytical question determines which calculation is appropriate and what the visual emphasis should mean.
Visualizing PageRank and Centrality
Centrality measures describe different aspects of a node’s structural role. In a simple undirected graph, degree centrality expresses the proportion of other nodes to which a node is directly connected. Betweenness centrality measures its participation in shortest paths between other nodes. A node with relatively few connections can therefore have high betweenness if many shortest routes pass through it.
Eigenvector centrality accounts for the centrality of connected nodes. For directed graphs, NetworkX calculates it from incoming connections. This makes the meaning and direction of the relationships important when interpreting the result.
PageRank also evaluates nodes through incoming links, accounting for the scores of the linking nodes and how they distribute their outgoing connections. In a web graph, nodes represent pages and directed edges represent hyperlinks. A page can receive a high score through links from other high-scoring pages, even if it does not have the greatest number of incoming links.
Mapping PageRank scores to node size or color makes those differences visible within the network. Larger or darker nodes can indicate higher scores, while the layout shows their surrounding connections. A node’s position near the center of the drawing does not establish its rank; the visual encoding must reflect the calculated values.
Community Detection and Visual Clustering
Community detection algorithms group nodes according to defined connectivity criteria. Their output can be mapped to node colors, making it possible to examine relationships within each community and connections between groups. The selected algorithm matters because different methods can produce different assignments for the same graph.
A force-directed layout may place densely connected nodes close together, but visual proximity alone does not establish community membership. Coloring nodes by the calculated assignments allows the drawing to communicate the analytical result even where the layout does not separate the groups clearly.
Visualizing Paths and Graph Structures
A shortest-path calculation identifies a route according to the selected cost model. In an unweighted graph, that usually means the fewest edges. In a weighted graph, the calculation can minimize a value such as total distance. Highlighting the resulting edges against a subdued view of the surrounding network shows exactly which relationships form the route.
A minimum spanning tree answers a different question. For a connected, undirected weighted graph, it connects all nodes with the lowest total edge weight and no cycles. Displaying those selected edges within the original graph makes it possible to inspect which connections were retained. This structure does not necessarily preserve the shortest routes between individual node pairs.
Temporal Networks and Dynamic Views
NetworkX can analyze graph snapshots representing different periods. A communication network, for example, might contain the same participants across two snapshots but different connections or interaction frequencies. Comparing those states can reveal how the observed relationships have changed.
Stable node identifiers allow corresponding entities to be matched across snapshots. Reusing positions for existing nodes where practical, together with consistent color and size scales, helps readers distinguish changes in the data from changes introduced by the drawing. Animating the comparison or updating it continuously requires additional rendering and application logic.
Random Graphs for Comparison
NetworkX graph generators can create reference networks for examining whether an observed property is unusual under a specified model. The model should reflect the question being investigated. A comparison of clustering needs to account for relevant characteristics such as network size and density before differences can be interpreted meaningfully.
Visual inspection can help identify structures worth investigating. Repeatedly generating reference graphs and comparing calculated metrics provides a firmer basis for assessing those differences than the appearance of a single drawing.
Practical Applications of NetworkX Graph Visualization
In social network analysis, NetworkX can model relationships between people or organizations and calculate properties of their connections. A communication graph can represent observed exchanges between teams and show where particular participants connect otherwise separate groups. Coloring nodes by calculated community assignments makes those groups visible, while highlighting selected paths helps an analyst examine how they are connected.
Biological network analysis applies similar methods to relationships such as protein interactions. A visualization can place an individual protein within its surrounding interaction network and show whether it connects to a densely linked group. Interpreting that structure requires biological context: a cluster of connected proteins may warrant investigation, but its functional significance depends on supporting annotations and experimental evidence.
In computer science, the graph model depends on the system being examined. A web crawler can supply pages and hyperlinks for analyzing the structure of a website. A software dependency graph instead records which components rely on others, allowing developers to inspect indirect dependencies before making a change. Network traffic can also be represented as connections between devices, with edge attributes recording observed communication volumes. The visualization makes those relationships available for inspection, while conclusions about bottlenecks or operational impact require the relevant measurements.
NetworkX Graph Visualization Best Practices
A useful NetworkX visualization begins with a question that the intended audience needs to answer. Investigating the potential impact of a component failure requires a different view from comparing communities across a social network. That purpose should guide which relationships are included and how much detail the drawing presents.
Handling Large NetworkX Graphs
A large graph can exceed the practical limits of a readable drawing before it exhausts the available memory. For an investigation centered on one entity, a relevant subgraph may expose the relationships needed for the task more clearly than a complete network view. Aggregating related nodes can provide an overview, provided that readers can understand what each aggregate represents.
Reducing the displayed graph and reducing memory consumption are separate concerns. NetworkX stores graph structures and attributes in Python objects, so loading unnecessary attributes or maintaining multiple graph copies can add substantial overhead. A subgraph view can avoid creating an independent copy, but the original graph remains in memory. Sparse arrays can support suitable numerical calculations; retaining both representations also retains their combined memory requirements.
Measure analytical computation separately from layout and rendering. Reusing results can avoid unnecessary work when the graph, selected parameters, and analysis scope remain unchanged.
Choose and Reuse an Appropriate Graph Layout
The choice of graph layout should support the relationships readers need to follow. A force-directed arrangement can provide an overview of connectivity, while a layered arrangement may make the direction of dependencies easier to trace. Circular or shell layouts can be useful when node ordering or defined groups provide the basis for the comparison.
For an unchanged graph, reuse calculated positions when adjusting its presentation. A fixed random seed can make a randomized layout reproducible for the same graph and software environment, but retaining the actual coordinates gives direct control over placement across repeated views.
Map Visual Properties to Defined Data
Visual scales need to remain consistent wherever readers are expected to compare values. If each filtered view rescales node sizes independently, two equally sized nodes may represent different centrality scores. Either preserve the comparison scale or make the change explicit.
The scope of the calculation also matters. A score calculated on the complete network can differ from one calculated only on the displayed subgraph. Readers should be able to establish which graph the metric describes before interpreting the visual emphasis.
Use Labels, Legends, and Annotations Selectively
Labels should identify the elements needed for the current task. In an interactive view, hover information can provide supporting attributes without placing every value permanently on the drawing. A static report may instead need selected labels and a separate explanation of the highlighted relationships.
Legends should explain the visual encodings and identify units where applicable. An annotation can then explain a specific finding, such as why a route was selected or which connection requires attention.
Test and Refine the Visualization
Evaluate the drawing against a concrete task. A reader investigating a dependency should be able to locate the relevant component and follow the relationships that explain its potential impact. If that requires searching through overlapping labels or guessing the meaning of an edge, revise the view before adding more information.
Check highlighted findings against the source data and calculated results. Comparing alternative layouts can reveal whether a particular arrangement makes an established relationship easier to follow or merely gives it greater visual prominence.
Troubleshooting NetworkX Graph Visualization Issues
A NetworkX drawing can only represent the graph and visual parameters supplied to it. When the result differs from expectations, first check whether the graph contains the correct entities and relationships. Then verify that each displayed node has a layout position and that styling values correspond to the elements being drawn. Error messages can help identify which stage of this process has failed.
|
Problem |
What to Check |
Recommended Action |
|
The graph does not appear |
Figure display and plotting environment |
Confirm that the Matplotlib figure is displayed and that the selected backend supports the intended output, particularly in notebooks or automated reporting environments. |
|
Expected nodes or edges are missing |
Source records, identifiers, and graph class |
Inspect the stored graph before drawing it. Distinct entities need distinct identifiers, and separate relationships between the same endpoints require a graph class that preserves parallel edges. |
|
Stored attributes do not change the appearance |
Attribute-to-visual mappings |
Explicitly map the required attributes to drawing properties. An edge’s weight does not automatically determine its line width, although layout functions may use it when calculating node positions. |
|
Colors or sizes appear on the wrong elements |
Element ordering |
Build styling values in the same order as the node or edge list used for drawing. Check that the number of values matches the selected elements. |
|
The layout changes between runs |
Randomized initialization |
Set a fixed seed where supported. Reuse calculated node positions when comparing different presentations of the same graph. |
|
Nodes and labels overlap |
Graph density, layout, and available space |
Test a layout suited to the structure and adjust the figure dimensions. Where the view remains crowded, display a relevant subgraph and label selected elements. |
|
Directed relationships lack visible direction |
Graph model and arrow settings |
Preserve relationship direction with DiGraph or MultiDiGraph, then check that arrowheads are visible at the selected node size and drawing scale. |
|
The visualization is slow |
Analysis, layout, and rendering time |
Measure these stages separately. Reduce the displayed detail where appropriate and reuse calculations whose inputs have not changed. |
NetworkX automatically creates endpoint nodes when edges reference identifiers that are not already present. An unexpected node may therefore indicate an inconsistent identifier in the source data rather than a drawing error.
Failures in an analytical calculation require a separate diagnosis. If PageRank does not converge, review its iteration limit and tolerance in relation to the graph and required accuracy before attempting to visualize the result.
When to Use NetworkX for Graph Visualization
NetworkX is a practical choice when graph construction and analysis form part of an existing Python workflow. Researchers and developers can inspect relationships as they refine a model, compare algorithm results, and prepare visualizations for notebooks or reports. Its drawing functions provide direct control over how those results are presented, while additional libraries can support interactive exploration.
Developing an application for end users introduces further design requirements. Users may need to move from an overview to a selected entity, inspect its relationships, and retain the context of their investigation as the view changes. The development approach must account for those interactions and how they connect to the underlying data and analytical methods.
Tom Sawyer Perspectives provides a low-code development platform for building custom graph and data visualization applications. It brings data integration together with automatic graph layout, graph analysis, and interactive graph visualization. Users can apply its integrated graph analysis algorithms to a graph or selected subgraph without writing code. Applications can be deployed independently or incorporated into existing systems, allowing development teams to build workflows around the connected data their users need to examine.
About the Author
Max Chagoya is an Associate Product Manager at Tom Sawyer Software. He works closely with the Senior Product Manager performing competitive research and market analysis. He holds a PMP Certification and is highly experienced in leading teams, driving key organizational projects and tracking deliverables and milestones.
FAQs About NetworkX Graph Visualization
What is the difference between NetworkX and Matplotlib?
NetworkX is a Python library for creating and analyzing graphs, while Matplotlib is a general-purpose plotting library. NetworkX layout functions calculate node positions, and its standard drawing functions use Matplotlib to render the graph.
How can you compare multiple NetworkX graph layouts?
Apply different layouts to the same graph while keeping visual properties and drawing dimensions consistent. The comparison can be automated to produce several views, each showing a different arrangement of the same relationships. For randomized layouts, use a fixed seed where supported. Evaluate which arrangement makes the relevant connections easier to follow; changing node positions does not change the graph’s relationships or analytical results.
How do you save a NetworkX graph visualization?
For a graph drawn with Matplotlib, use its figure export functionality. PNG provides a raster image, while SVG or PDF can preserve vector elements for resizing and publication. Check label placement at the intended output size, and save the figure before closing it. In a pyplot workflow, saving before a blocking display call avoids attempting to export a figure that has already been closed.
How do you export NetworkX graph data for another visualization environment?
NetworkX supports graph exchange formats such as GraphML, GEXF, and GML. It can also generate node-link data suitable for JSON serialization. Choose a format supported by the receiving environment, then check that the imported graph preserves relationship direction and any parallel edges.
The exported graph does not automatically reproduce the original drawing. Layout coordinates and styling need to be stored in compatible attributes and interpreted by the receiving application to preserve the presentation.
How does NetworkX handle missing or incomplete graph data?
NetworkX represents the entities and relationships supplied to it; it does not identify records missing from the source. An absent edge may mean that no relationship exists or that the evidence is incomplete. Missing attribute values therefore need to be distinguished from missing entities or relationships. Where uncertainty matters, represent it explicitly in the data model so that a proposed connection can be displayed differently from a confirmed one.
Submit a Comment